Claude Opus 5.5 at 40% of Fable's price
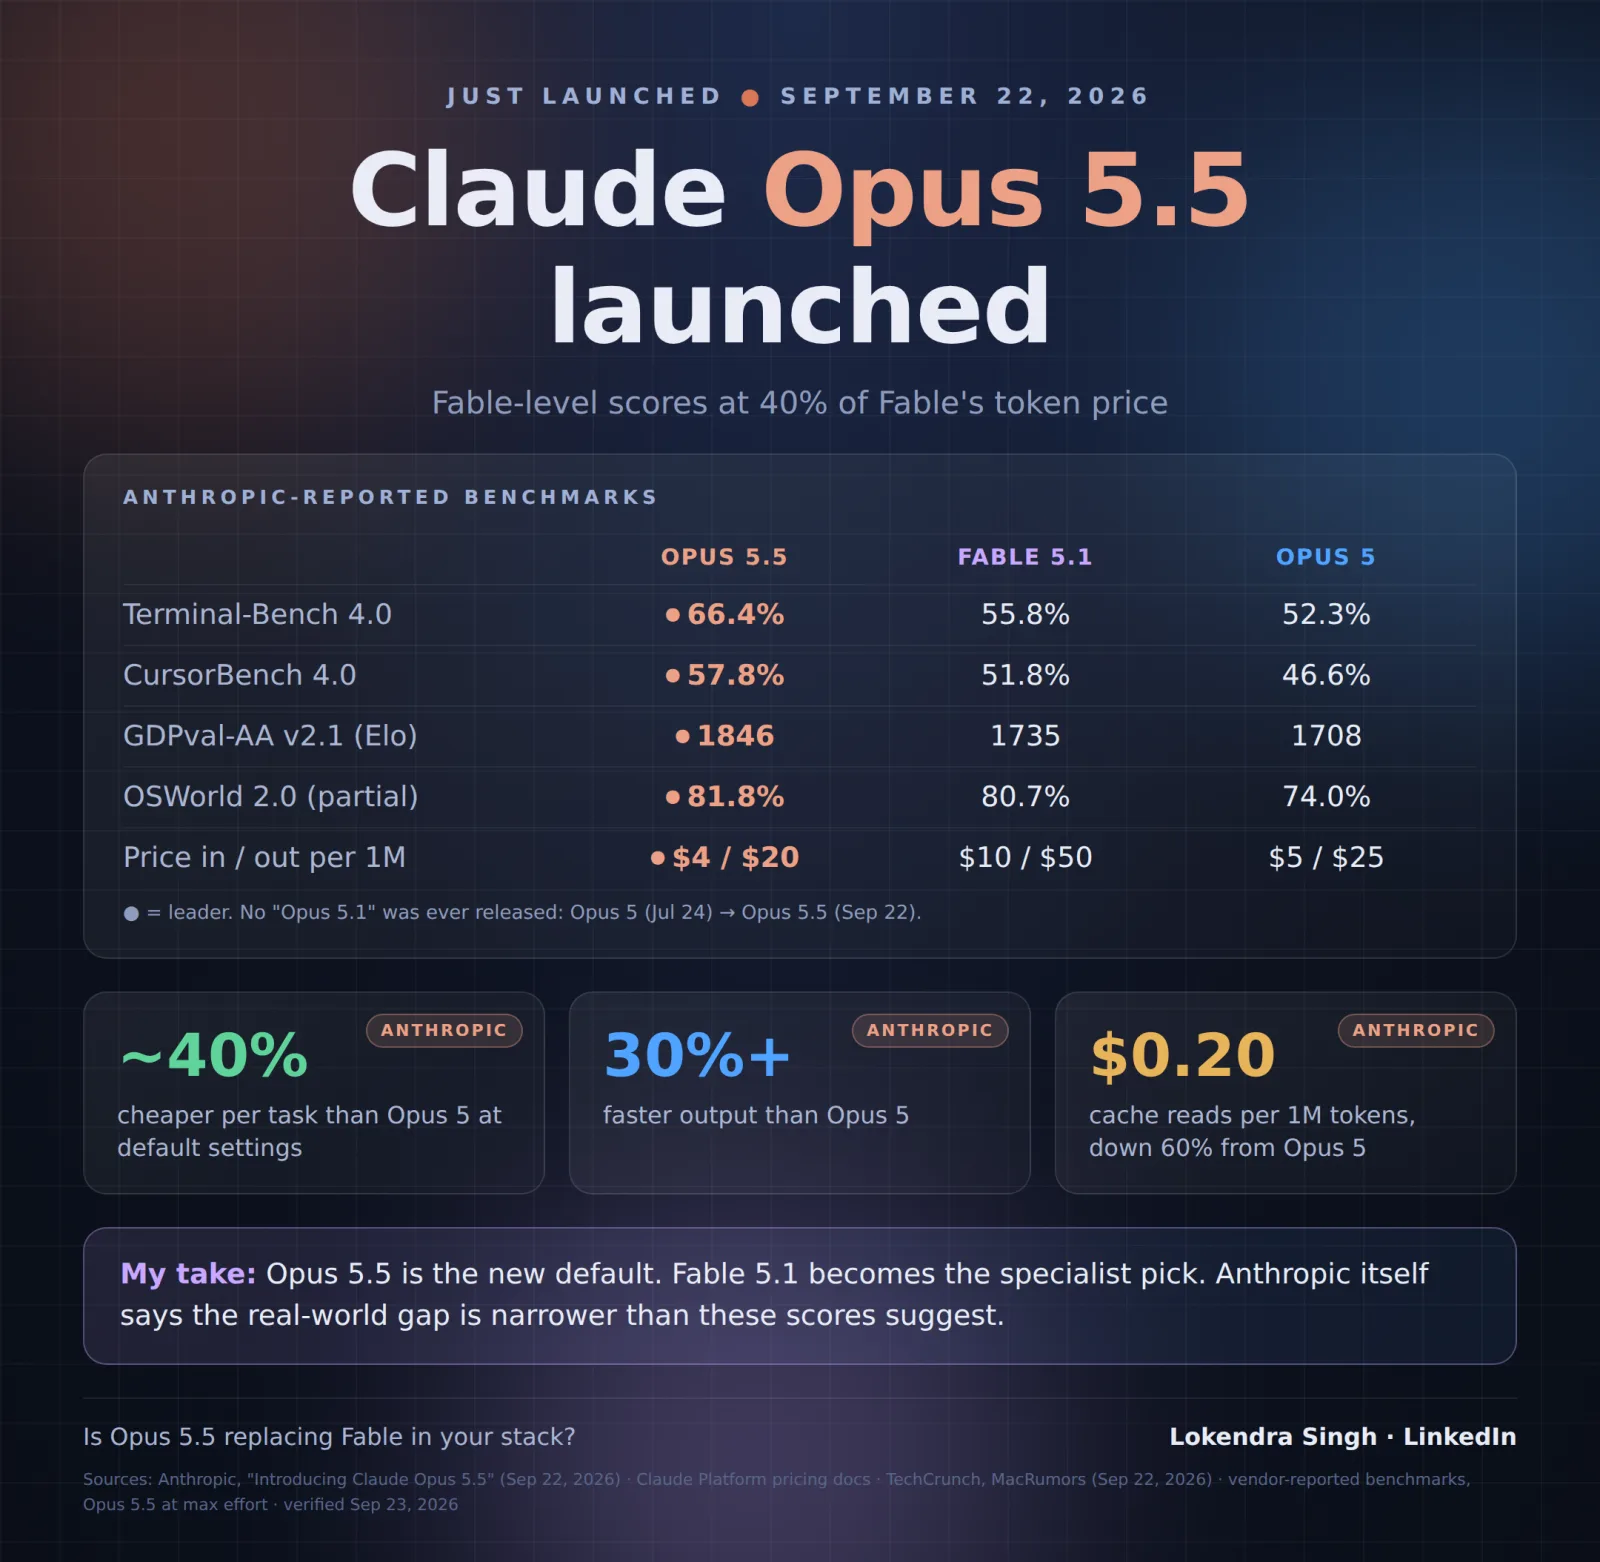
Claude Opus 5.5 launched on 22 September. It beat Fable 5.1 on every benchmark Anthropic published, at 40% of Fable's token price.
Before anyone asks: there is no Opus 5.1. It went Opus 5 (24 July) → Opus 5.5.
Price per 1M tokens
| Model | Input | Output | Cache read |
|---|---|---|---|
| Opus 5.5 | $4 | $20 | $0.20 |
| Opus 5 | $5 | $25 | $0.50 |
| Fable 5.1 | $10 | $50 | $0.25 |
Anthropic says ~40% cheaper per task than Opus 5, and 30%+ faster output.
Opus 5.5 vs Fable 5.1 vs Opus 5
| Benchmark | Opus 5.5 | Fable 5.1 | Opus 5 |
|---|---|---|---|
| Terminal-Bench 4.0 | 66.4% | 55.8% | 52.3% |
| CursorBench 4.0 | 57.8% | 51.8% | 46.6% |
| GDPval-AA (real work) | 1846 | 1735 | 1708 |
| OSWorld 2.0 (computer use) | 81.8% | 80.7% | 74.0% |
What that looks like in practice
- Early tester: a 200K-line codebase audited and fixed in under 3 hours. Opus 5: 20+ hours.
- Anthropic's own test: HAProxy ported from C to Rust in 9.5 hours vs Fable 5.1's 12, at 51% lower cost.
- Deloitte: at its lowest effort it caught 72% of known bugs, vs 56% for Opus 5 at high effort.
What else changed
- First Opus with Fable-class safeguards. Most cyber requests fall back to Opus 4.8.
- Thinking can no longer be switched off.
- Sonnet 5.5 and Haiku 5.5 "in the coming weeks".
The honest part
- Every score above is Anthropic-reported. Wait for independent leaderboards before trusting the margins.
- Anthropic itself says the real-world gap to Fable 5.1 is narrower than these numbers suggest.
- Anthropic also flags that the model often suspects it is being evaluated.
My take
Opus 5.5 is the new default. Fable 5.1 just became a specialist tool you reach for only after Opus 5.5 fails on your task.
Is Opus 5.5 replacing Fable or Opus 5 in your stack?
Sources
- Anthropic - Introducing Claude Opus 5.5 (22 Sep 2026)
- Claude Platform pricing docs
- TechCrunch and MacRumors (22 Sep 2026)