NVIDIA shrank a supercomputer to 1.2 kg
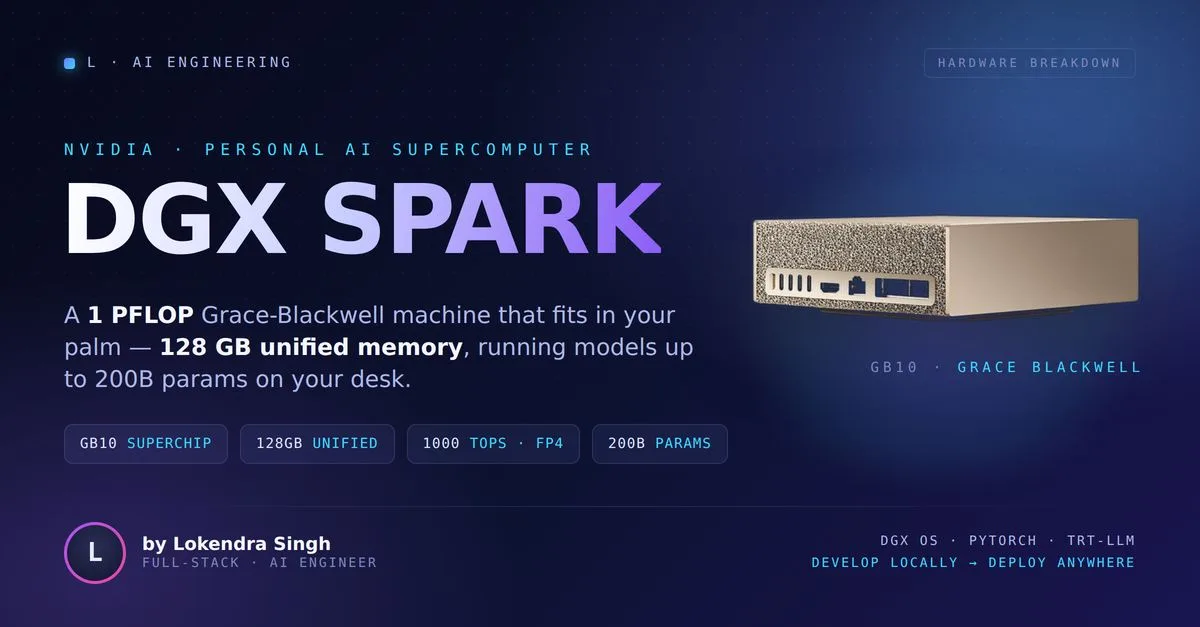
🧠 NVIDIA just shrank an AI supercomputer down to 1.2 kg.
The DGX Spark is a 150mm box running the Grace Blackwell GB10 Superchip - and for local AI development, it's one of the most interesting machines of 2026.
Ref: docs.nvidia.com/dgx/dgx-spark/hardware.html
Straight from NVIDIA's spec sheet 👇
The hardware
- GB10 Grace Blackwell Superchip
- 20-core Arm CPU - 10× Cortex-X925 + 10× Cortex-A725
- Blackwell GPU · 6,144 CUDA cores · 5th-gen Tensor Cores (FP4)
- 128 GB LPDDR5x unified memory (CPU + GPU share ONE pool)
- 1TB / 4TB self-encrypting NVMe
- ConnectX-7 + dual QSFP, Wi-Fi 7, 10 GbE
- Ships with DGX OS + the full NVIDIA AI stack (PyTorch, TRT-LLM)
Why developers should care
Unified 128 GB means no manual VRAM partitioning. Prototype, fine-tune, and run reasoning models up to 200B params locally - link two units over QSFP and you reach ~405B (Llama 3.1 405B territory). Develop on your desk → deploy to DGX Cloud or any data center with virtually no code changes.
The honest part (specs ≠ reality)
That headline "1 PetaFLOP" is FP4 with sparsity - dense compute is roughly half. The real ceiling is memory bandwidth: 273 GB/s, while Apple's M-series unified memory pushes 800+ GB/s. Translation: Spark isn't a tokens-per-second champion. Its superpower is FITTING large models locally, not raw throughput.
The reality check
~₹4.6L+ in India (via ThinkRobotics). At that price, it sits beside a tuned RTX 4090 rig or a maxed Mac Studio. Choose Spark for: CUDA-native workflows, big-model experimentation, and a clean local → cloud path.
My take
Not a cloud killer. A prototyping powerhouse that frees your cluster for the jobs that actually need it.
🎥 Krish Naik posted a solid hands-on unboxing + DGX OS walkthrough - worth a watch if you're weighing one up. Krish Naik: youtube.com/watch?v=I2dFW8L2jLQ&t=191s
Would you put one on your desk? 👇
// Originally posted on LinkedIn ↗